Hidden gems comes to Best-o-Masto on the web
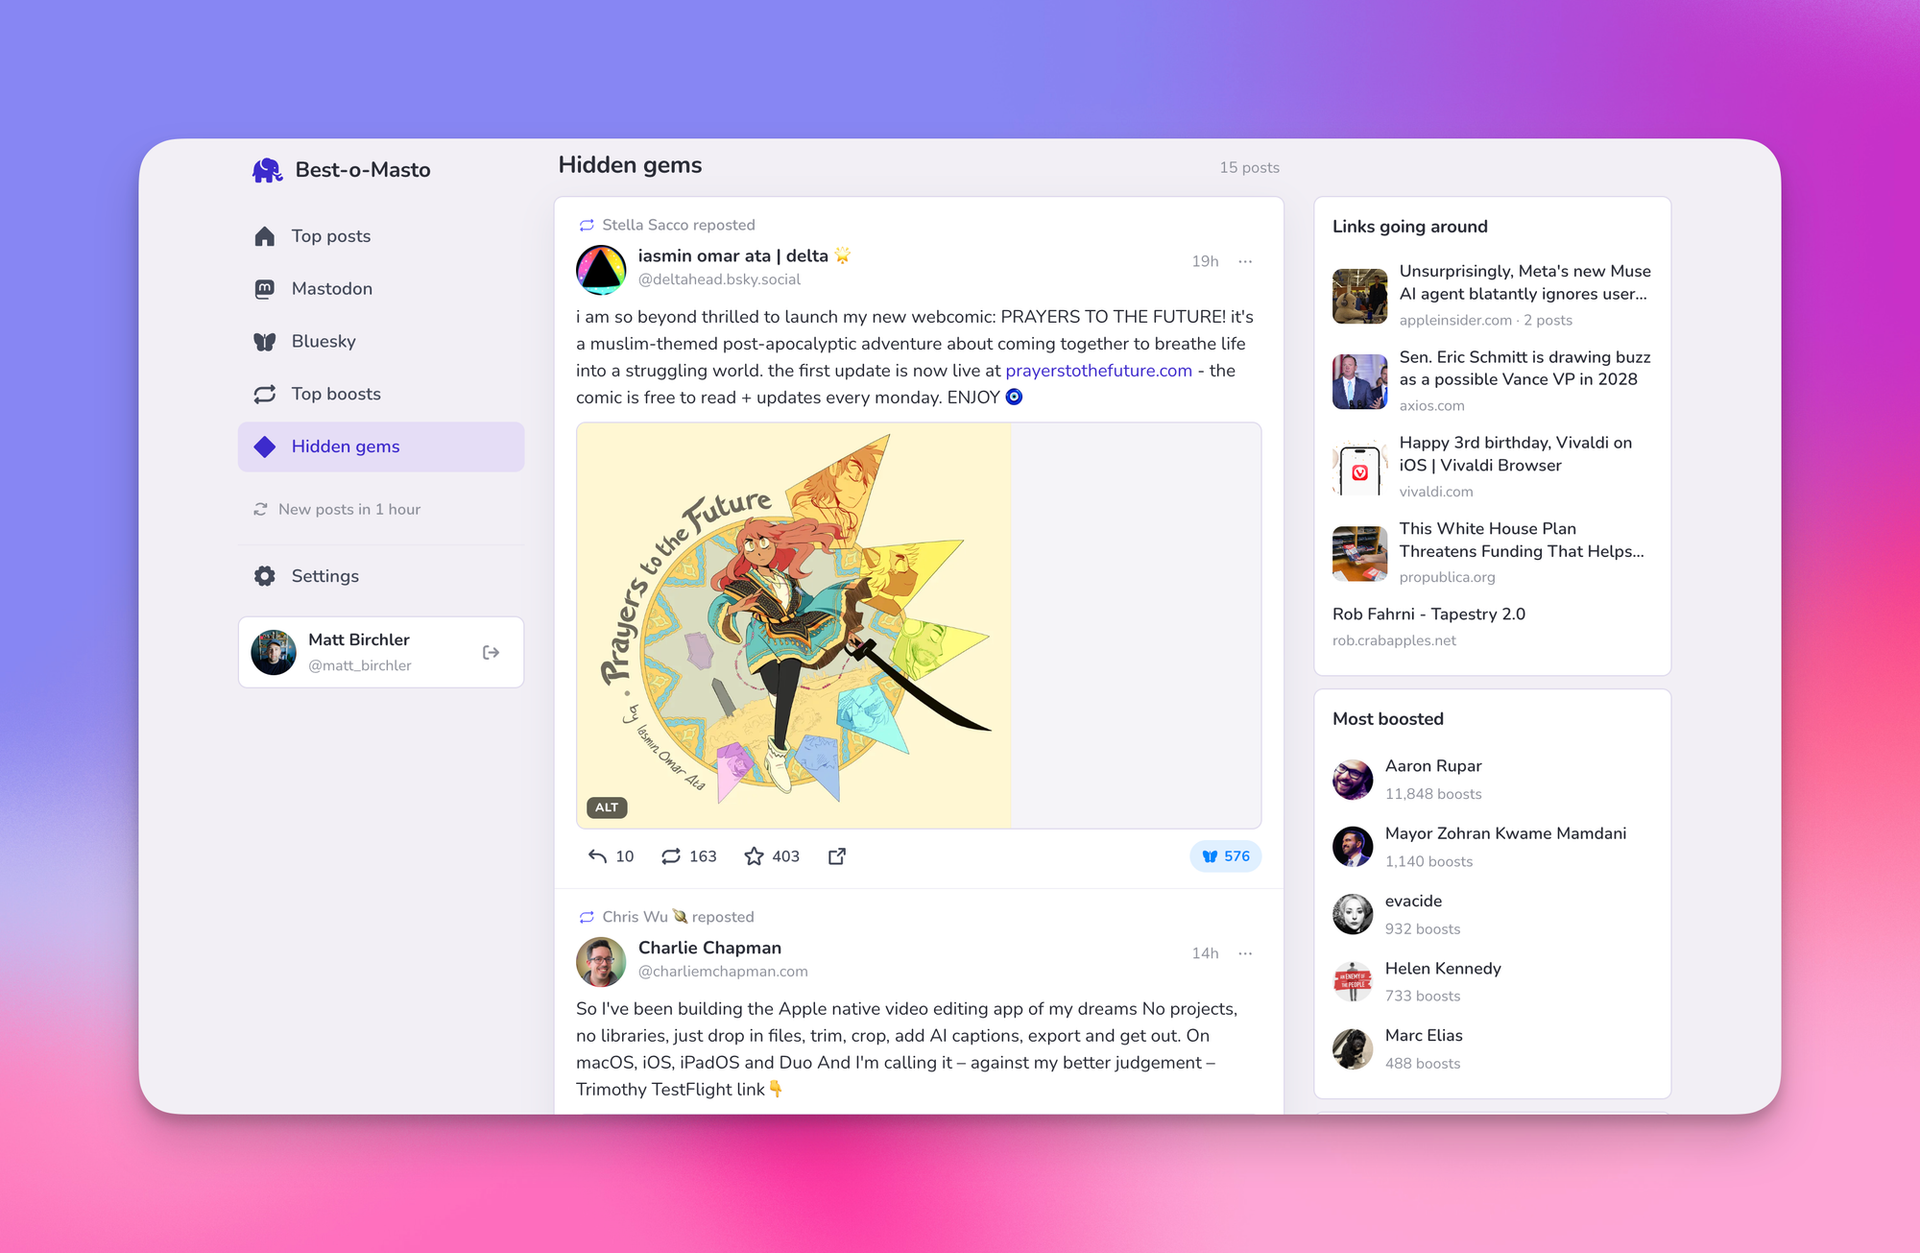
Best-o-Masto is my website for finding the best stuff from your Mastodon and Bluesky feeds quickly. It's not an algorithmic feed like you'd see on something like X or Threads. It's a very simple thing that finds the post getting the most engagement in your feed and serves those first.
The iOS app has had a feature since launch called "hidden gems", and the idea of Hidden Gems is that not all of the posts you might want to see are going to get the most boosts and favorites. Hidden Gems attempts to surface these interesting posts that maybe didn't get as many engagements, but you still probably want to see. That feature has been powered by Gemini since launch, and it works fine, but it's slow and costs real money to run. As such, I've always made it available exclusively as a bring your own API key situation rather than something just built into the app.
But recently, a new model came out called Jev, which is not a language model – it's effectively a decision engine which can (relatively) intelligently classify things for you. It's also incredibly fast and incredibly cheap. The metrics vary by what exactly you're doing, but we're talking in the order of being 200x faster and 400x cheaper in some cases.
Of note, this feature is completely opt-in for users, so if you have no interest in this sort of feature, just don't use it.
The feature is in beta as I monitor costs/reliability.
How it actually works
This might be interesting because it is different from other LLMs. In a way, integrating to a large language model is the simplest API you've ever used because you just kind of toss in whatever text you want and it figures it out, giving you text back.
We're about to get into the weeds, but I think showing actual code is going to be helpful here to understand how this works. Using some completely made up posts, here's an example of what the request looks like when I look for hidden gems.
{
  "model": "typesafe/jev-1.13",
  "state": "POST 1\nFinally finished the quilt I started in 2019. Four moves and one pandemic later.\n[2 images, alt: A blue and white patchwork quilt draped over a chair]\n\nPOST 2\ngood morning everyone",
  "questions": {
    "p1": {
      "type": "score",
      "instructions": "Consider POST 1 only. How interesting would this social media post be to a reader who follows the author, ignoring how popular it is?",
      "criteria": [
        "Mundane, low-effort, a bare link, a greeting, or a reply that needs missing context",
        "Mildly interesting but forgettable",
        "Worth reading: a good joke, real insight, personal story, life event, or creative work",
        "A standout the reader would be sorry to have missed"
      ]
    },
    "p2": {
      "type": "score",
      "instructions": "Consider POST 2 only. How interesting would this social media post be to a reader who follows the author, ignoring how popular it is?",
      "criteria": [
        "Mundane, low-effort, a bare link, a greeting, or a reply that needs missing context",
        "Mildly interesting but forgettable",
        "Worth reading: a good joke, real insight, personal story, life event, or creative work",
        "A standout the reader would be sorry to have missed"
      ]
    }
  },
  "provider": {
    "data_collection": "deny",
    "zdr": true
  }
}
This sample only sends two posts, but in reality I pass in the text of several hundred posts in the state variable, then I pass questions where it looks at specific posts in the state, and it determines a score for each one. Each post can get a score from 0-3, with 3 being the most likely hidden gem. Because Jev is not a language model, it doesn't generate text in its response. All it does is take a look at the state, the instructions, and decides which criteria it meets. It does that across every single question provided.
Here's an example response:
{
  "model": "typesafe/jev-1.13-20260917",
  "answers": {
    "p1": {
      "type": "score",
      "score": 2,
      "legend": {
        "0": "Mundane, low-effort, a bare link, a greeting, or a reply that needs missing context",
        "1": "Mildly interesting but forgettable",
        "2": "Worth reading: a good joke, real insight, personal story, life event, or creative work",
        "3": "A standout the reader would be sorry to have missed"
      },
      "probabilities": { "0": 0, "1": 0.01, "2": 0.98, "3": 0.01 },
      "confidence": 0.98
    },
    "p2": {
      "type": "score",
      "score": 0,
      "legend": { "...same four lines..." },
      "probabilities": { "0": 1, "1": 0, "2": 0, "3": 0 },
      "confidence": 1
    }
  },
  "usage": {
    "input_tokens": 555,
    "output_tokens": 32,
    "cost": 0.00002331
  },
  "id": "gen-dec-1790707300-J2N6sJCCxL9IWgYlVnr5",
  "provider": "TypeSafe"
}
Here in the response, we can see that each question was scored. The first was scored a two, the second scored zero.
You can also see that there are probabilities assigned to each score, giving you an idea for what the odds are it falls into each category. There's also a confidence score of how confident it is in its assessment. Both of these were pretty straightforward, but as you get more complex content, the answers may be a bit fuzzier.
As a developer, the next step is pretty darn easy. Now I have a list of posts with scores attached to them, and I can just sort from biggest to smallest, displaying the 3s, then the 2s, and the 1s. The idea of this product is not to show you every single post in your feed, so it cuts off after the first 15.
Future Plans
I've always really enjoyed the feature in concept on iOS, although I've always felt a little bit disappointed by it in execution, largely because I require users to bring their own API key since I'm not able to absorb the costs, and it's just fundamentally slow because you're passing a lot of information into a language model and waiting for it to generate a full response with the post IDs it thinks are interesting. This has led to me personally not using this feature much.
This new implementation is really interesting because the results seem quite good in my testing so far, the performance is radically better, and the cost is seemingly negligible. I'll be closely monitoring my spending to make sure it doesn't get out of control, but it looks like this is something I can just offer for free on the web. If it stays okay, it'll be something I bring to the iOS app as well.